

AI traffic · Perplexity
Perplexity traffic: what it fetched, and who clicked
Perplexity traffic starts long before anyone clicks. PerplexityBot indexes your pages, Perplexity-User reads them while someone waits, and some readers follow the citation. Skald shows each one apart.
Perplexity traffic is everything Perplexity does on your website: PerplexityBot crawling to build its index, Perplexity-User fetching a page at the moment someone asks a question, and people who click a citation from perplexity.ai. A script tag sees only the last. Your server log holds all three.
30-day free trial · no card · we set it up within one working day · free to self-host
PerplexityBotindexes ahead of any question
Perplexity-Userfetches when someone asks
- index crawls
- 152
- live fetches
- 197
- people sent
- 46
Sample month. Three counts that never add up to one: two machines and the people who followed them.
[01] your rules
You blocked AI training. Perplexity still reads every page.
PerplexityBot builds a search index and Perplexity-User answers one person's question. Neither trains a model, so "block training only" refuses neither. Pick a rule and watch which tiles turn over. One part of AI traffic tracking.
GPTBot, ClaudeBot and anthropic-ai are refused. Perplexity has no training crawler in the list, so both of its tiles stay in.
your settings
{"owners": {"OpenAI": "block_training",
            "Anthropic": "block_training",
            "Perplexity": "block_training"},
 "crawlers": {}}
the nginx file Skald writes from them
map $http_user_agent $skald_block_agent {
    default 0;
    "~*GPTBot" 1;
    "~*ClaudeBot" 1;
    "~*anthropic-ai" 1;
}
Three of the companies behind the 39 crawler names Skald knows, with sample settings. The tiers and the file are the code's own (bot_policy.py): nginx, the web server in front of many sites, reads it. robots.txt, the file where a site asks crawlers to stay away, is always answered, so a refused crawler can still read your rules.
[02] is it really Perplexity
Anyone can call itself PerplexityBot. Two lists say who is real.
Perplexity publishes one address list for PerplexityBot and one for Perplexity-User. Skald checks a request against both, because both belong to one owner. It calls a request a fake only when both lists are fresh. With one list too old, it says it cannot tell.
203.0.113.51 "GET /compare/" "PerplexityBot/1.0"
addresses 203.0.113.0 to 203.0.113.255 · sample ranges
perplexitybot.json fetched 1 day ago
perplexity-user.json fetched 1 day ago
verdict
Verified
On perplexitybot.json. Counted as PerplexityBot, with the crawls that train or index, under its own name.
The order is the code's (bot_verify.py): on any of the owner's lists, verified; on none, a fake only if every list is 7 days old or less; otherwise not verifiable.
[03] the people it sent
A Perplexity click rings in four ways. One name answers.
A click's caller ID is its referrer, the address of the page it came from. The website, its subdomains, the Android app and a utm tag (a utm_source= label on the link) all mean Perplexity. Count them as they come and Perplexity is three rows in your sources. Skald files them as one: perplexity.ai. A visit with no caller ID is only ever "likely", and kept apart.
Sample month. 46 and 23 are never added: the 23 stay "Direct or unknown" in every count.
caller ID
https://www.perplexity.ai/
"GET /pricing/" ref https://www.perplexity.ai/
filed as
People · source perplexity.ai
The referrer's host is perplexity.ai or one of its subdomains, so Skald names it Perplexity.
Before the click, Perplexity-User fetched /pricing/ 1 minute before and /reviews/ 2 minutes before.
[04] when it changes
Perplexity sent you three times its usual. You hear about it the next morning.
Skald compares yesterday's visits likely sent by Perplexity with its daily average over the 28 days before. A jump to 3 times the average, and at least 10, is an alert. So is a drop to 10% of an average of 5 or more. Below both, it says "too few to judge" and stays quiet.
28 days beforeyesterday
what Skald does
Alert: perplexity.ai jumped
perplexity.ai likely sent 24 visits on Fri 23 Oct
Visits likely sent by perplexity.ai on Fri 23 Oct (2026-10-23): 24. Its daily average over the 28 days before (2026-09-25 to 2026-10-22): 6.2. Jumped: 3x the average and 10+.
Sample days. The words are the alert's own (alerts_ai.py), built on likely visits that a second count already checked. A day is judged only when all 29 days were counted.
- Started reading Perplexity fetched a page yesterday that it had not fetched in the 28 days before.
- Stopped reading A page Perplexity fetched in at least 3 of the 4 weeks before has gone 7 days without a fetch.
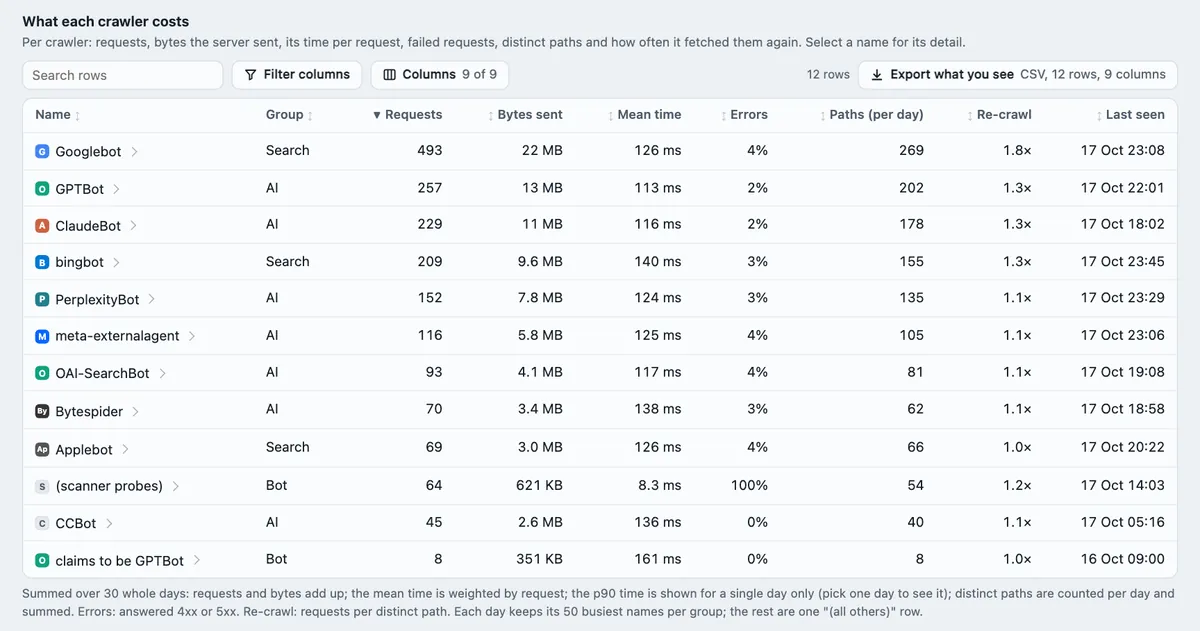
Each real Perplexity fetcher also gets a cost and a share of your sitemap reached. AI crawl health
[05] what it cannot see
Where Perplexity traffic tracking stops
Skald sees what reaches your server log, and no more. These are the gaps.
What it does not do
- It does not know what Perplexity tells each person. AI answers samples answers with your own API keys, as a direction over weeks.
- Clicks from Perplexity are a floor. Likely visits are an estimate, kept apart, never added.
- A user agent is self-reported. A fetcher that hides its name cannot be told apart from a reader.
- Without a server or CDN log (a CDN, such as Cloudflare, is a service that serves your pages from near each reader), Perplexity's fetches are not seen at all.
keep reading
More on Perplexity traffic
questions
Perplexity traffic FAQ
Straight answers, including what Skald does not do.
How do I track traffic from Perplexity?
People who click a citation arrive with perplexity.ai as the referrer, and any analytics tool counts them. Perplexity's own fetches, by PerplexityBot and Perplexity-User, never run a script, so only your server log shows them. Skald reads both from the log and keeps them apart.
What is the difference between PerplexityBot and Perplexity-User?
PerplexityBot crawls ahead of any question to build Perplexity's index. Nobody is waiting on it. Perplexity-User fetches a page because one person asked Perplexity something just then. Skald counts the first with the training crawls and the second as a live fetch.
Is that PerplexityBot really Perplexity?
Skald checks it. Perplexity publishes the addresses of PerplexityBot and of Perplexity-User, and Skald compares every request with them. A request using the name from another address is filed under bots as "claims to be PerplexityBot".
Why do some Perplexity visits show as direct?
The referrer is often lost on the way, in apps or by privacy settings. When a direct visit lands on a page Perplexity-User fetched up to 15 minutes before, Skald marks it likely from Perplexity. It stays a direct visit in every count.
Does Block training only keep Perplexity out?
No. Perplexity's two crawlers build its search index and answer people's questions; neither is a training crawler. To keep Perplexity out, block the company, or block PerplexityBot on its own. How blocking AI crawlers works.
$ tail -f access.log | skald
See what AI does with your site. Free for 30 days.
No card. We set up hosted Skald for you within one working day, or you self-host it free. Every line of your log, sorted and added up.